
Definitions · HPC
What is HPC (high-performance computing)?
What is HPC? High-performance computing joins many processors to finish large jobs faster: what clusters need, and how compute is bought per job.
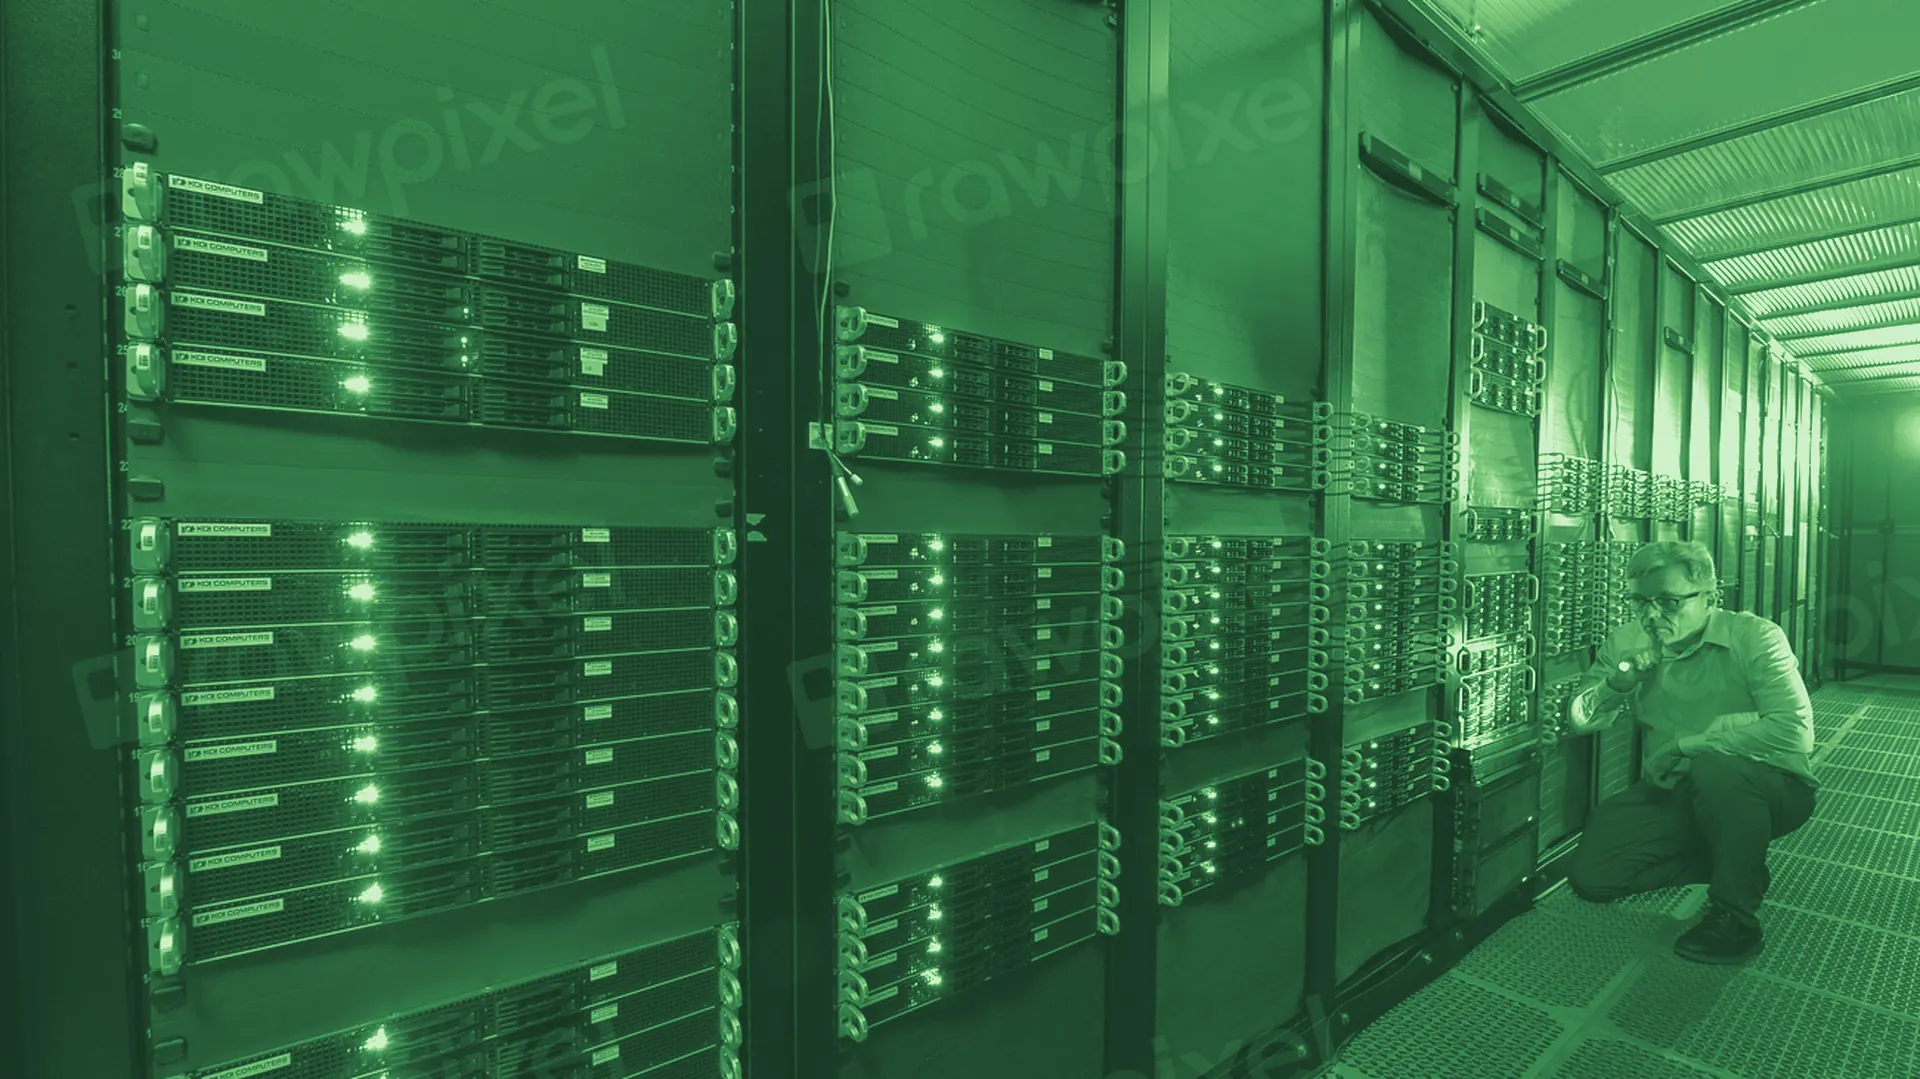
High-performance computing (HPC) is the use of large numbers of processors, memory and storage, joined into a single system or cluster, to finish computational jobs that would be impractical on an ordinary machine.
The work is typically numerical - simulation, modelling, rendering, risk analysis - and it splits into pieces that later have to exchange results. Two properties define the category: work is distributed across many nodes instead of running on one, and those nodes are connected by low-latency interconnects so that exchanging intermediate data does not become the slowest part of the job.
What a cluster is built from
HPC systems are assembled rather than bought as a unit:
- Compute nodes - machines with many cores and large memory footprints, frequently identical so jobs scale predictably across them.
- Interconnect - the fast fabric between nodes, on which tightly coupled jobs depend more than on anything else.
- Storage - parallel filesystems and scratch space sized to keep data near the nodes consuming it.
- A batch scheduler - the queue that admits jobs, allocates nodes and decides what runs next.
- Site services - power, cooling and physical access, which are operations rather than software but decide uptime all the same.
The hardware is the straightforward half. A cluster earns its keep when jobs arrive in a shape the scheduler can place: data staged close to compute, submissions written for the queue, failures expected and recovered from checkpoints rather than from the beginning.
Two of those are habits rather than features. Staging data near compute and writing submissions for the queue are choices the submitting team makes, and they separate a cluster that stays busy from one that spends its day waiting on jobs that could have started hours earlier. Hardware does not compensate for either mistake; it simply makes the wait more expensive.
Why HPC workloads behave differently
Tightly coupled jobs need whole nodes and a fast fabric, because every participant waits on the others; throughput jobs simply fill cores and care little about latency between nodes. Both are admitted through a batch queue rather than by requesting machines one at a time, and SLURM is the scheduler most often found in that role - submit, wait for allocation, run, release.
That queueing pattern is why HPC procurement has historically been a capacity decision rather than an on-demand one: a site buys for its peak workload and the scheduler smooths demand across it. The operational side of running this on VirtEngine - schedulers, adapters and job-shaped orders - is set out in HPC on VirtEngine.
The distinction shapes how capacity is planned. Throughput work spreads across whatever machines happen to be free and tolerates a busy queue; tightly coupled work cannot, because a single slow participant stalls everyone waiting on it. Sites respond by reserving the fastest fabric for jobs that will genuinely use it and pushing everything else to the general pool. Renters of the same systems face an echo of the question: whether a job needs a whole machine or only a share of one.
Who runs HPC workloads
Universities and research facilities simulate weather, materials, fluids and molecular behaviour; industry teams model vehicles, structures and risk; media studios render; and machine-learning training has become a frequent guest on the same machines, since it also wants many accelerators and a scheduler.
What these buyers share is a queue-shaped demand: occasional need for a lot of compute, deadlines that vary, and no desire to own a cluster that would sit between runs. That pattern is what makes per-job purchasing worth considering at all.
The other shared trait is unevenness. Work arrives in bursts around deadlines with quiet stretches in between, and a cluster owned outright is paid for during those stretches as well. A large site absorbs that by keeping one queue full across many groups; a single team cannot, which is why shared facilities and rented capacity exist as answers to the same arithmetic.
Compute sold by the job
On VirtEngine, an HPC requirement is written down rather than assumed: node count, duration, interconnect and storage expectations, plus the scheduler the job is written for. The tenant funds an escrow account with that request, so providers with free nodes can see committed budget before answering it, and bids compete on price and on what the site can actually offer.
Once matched, the lease is fulfilled through the provider's scheduler adapter, which places the job on real hardware and reports node-time as signed usage records. Settlement draws validated line items from escrow after the dispute window and returns whatever is unspent. Capacity and category detail sit with HPC listings on the market.
In practice
A job is described by node count, duration and fabric needs, escrowed by the tenant, then placed on a provider's cluster through its scheduler with node-time signed and settled afterwards.
Questions
Asked about what is hpc (high-performance computing)
What is HPC used for?
For computational work that needs many processors at once: simulation and modelling of weather, materials, fluids and molecules, engineering analysis, rendering, risk calculation, and machine-learning training. The common factor is a job that parallelises well across nodes.
What does a typical HPC system consist of?
Compute nodes with many cores and large memory, a fast interconnect between them, parallel or scratch storage, a batch scheduler that allocates nodes, and the site infrastructure supporting all of it. The scheduler and the fabric are what separate a cluster from a room full of servers.
How does HPC differ from ordinary cloud computing?
HPC jobs are parallel, often tightly coupled, and need whole nodes, low-latency networking and a queue. They are scheduled in blocks rather than provisioned per machine on demand, which changes both the architecture and the way compute is purchased.
Can HPC compute be bought for a single job?
That is the marketplace model: a job-shaped requirement is posted with node count, duration and interconnect, escrow funds it, and a provider with free capacity fulfils it through its scheduler. Usage is metered for the duration of the run and settles after the dispute window.
Related
Keep reading
- What is SLURM? SLURM is the cluster scheduler behind most HPC sites. What it controls, why it became the standard, and how its jobs reach the market.
- What is AI training? What is AI training? Fitting a model to data on accelerators: what a run needs, how it differs from inference, and where the capacity comes from.
- What is GPU as a Service? GPU as a Service rents accelerator capacity instead of buying servers. What the model covers, what a listing must state, and how usage settles.
- What is bare metal? Bare metal is a whole physical server for one tenant. When to choose it over virtual machines, what you take on, and how it is listed.
- What is a compute marketplace? A compute marketplace matches demand for capacity with providers who have it. How orders, escrow and signed usage become settled payment.
- All definitions Every cloud and marketplace term, defined in one place.
Longer explainers live in Learn; the full vocabulary is in the marketplace glossary.